
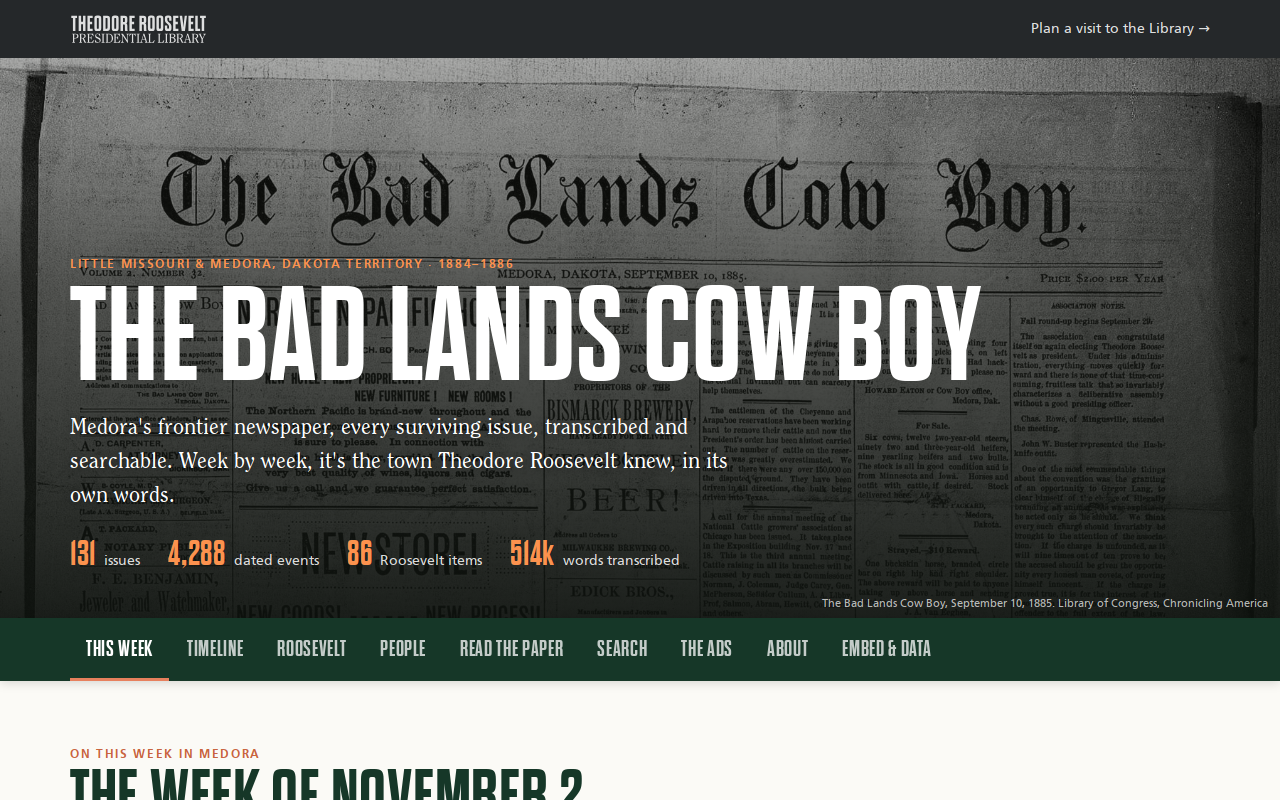
Try it right here
This loads the live project from its own domain, exactly as a visitor would see it.
Transcriptions were made with AI from the page images. Check any quotation against the scan before publishing; every item links to it.
What it does
The Bad Lands Cow Boy was Medora's newspaper from 1884 to 1886, the years Roosevelt ranched here. This site puts every surviving issue online, transcribed and indexed: what the paper reported for any calendar week, a timeline of more than 4,000 dated events, every item that names Roosevelt, full-text search of about half a million words, and a gallery of nearly 200 period ads and cattle brands.
Transcriptions sit beside the zoomable Library of Congress page scan, and clicking an item zooms the scan to it. A people index matches more than 1,800 names across the paper's spellings, with short bios written only from the paper's own items and fact-checked against the full text. Items from missing issues are recovered where other papers reprinted them.
What it can do
- "This Week in Medora" for any calendar week, embeddable and defaulting to today
- Timeline of dated events, filterable by month, topic, and person
- Transcription beside the page scan, with one-click zoom to each item
- Full-text search across the whole run
- Ad and brand gallery, each cropped from the scan where it first ran
- People index with fact-checked bios and highlighted mentions
- Events published as CSV and JSON
Make it your own
Start by forking the repository into your own organization. Everything below assumes you are working in your fork, not this one.
- Fork the repo and find your paper's LCCN on Chronicling America.
- Run
scripts/fetch_batch.pyandscripts/prep_blocks.pyto pull page OCR and block coordinates. - Transcribe each issue into
source/transcriptions/<date>.jsonfollowing the rules inscripts/TRANSCRIBE_BRIEF.md. - Run
python3 scripts/build_site_data.pyto compile the site data. - Enable Pages from
mainat the root and editCNAME.
Stuck on a step? Open an issue on the repository. Questions from people adapting these for their own institution are the most useful feedback we get.